 熊猫出海编辑团队
Last updated: 13 November 2026. All prices checked on the vendors’ official pages that day.
This LLM API pricing comparison puts the official list prices of the main model vendors side by side: OpenAI, Anthropic, Google, Mistral and DeepSeek, plus three popular platforms that host or route many models: OpenRouter, Together AI and GroqCloud. Every number was copied from the vendor’s own pricing page or model card on 13 November 2026, and each source is linked at the end. Where a vendor’s pages disagree or a price is scheduled to change, we say so.
Need deeper detail on one vendor? Read OpenAI API pricing, ChatGPT API pricing, Claude API pricing or Gemini API pricing. If your company wants to use several of these models without juggling accounts, see our Overseas AI Token service: account setup + API access (PandaWM).
Frontier and mid-tier models
| Frontier / mid model | Input / 1M | Output / 1M | Notes |
|---|---|---|---|
| OpenAI gpt-6.1-sol | $2.00 | $10.00 | gpt-6-astra: $10 / $50 |
| Anthropic Claude Sonnet 5.5 | $2.00 | $10.00 | Opus 5.5: $4 / $20 |
| Google Gemini 4 Argon | $2.00 | $10.00 | $4 / $20 from 1 Dec 2026 |
| Google Gemini 4 Hydrogen | $1.50 | $7.50 | Free tier available |
| DeepSeek V4 Pro | $1.32 | $3.96 | Peak rate; off-peak $0.66 / $1.98 |
| Mistral Large 4 | $0.70 | $2.10 | 1M context, GA 5 Nov 2026 |
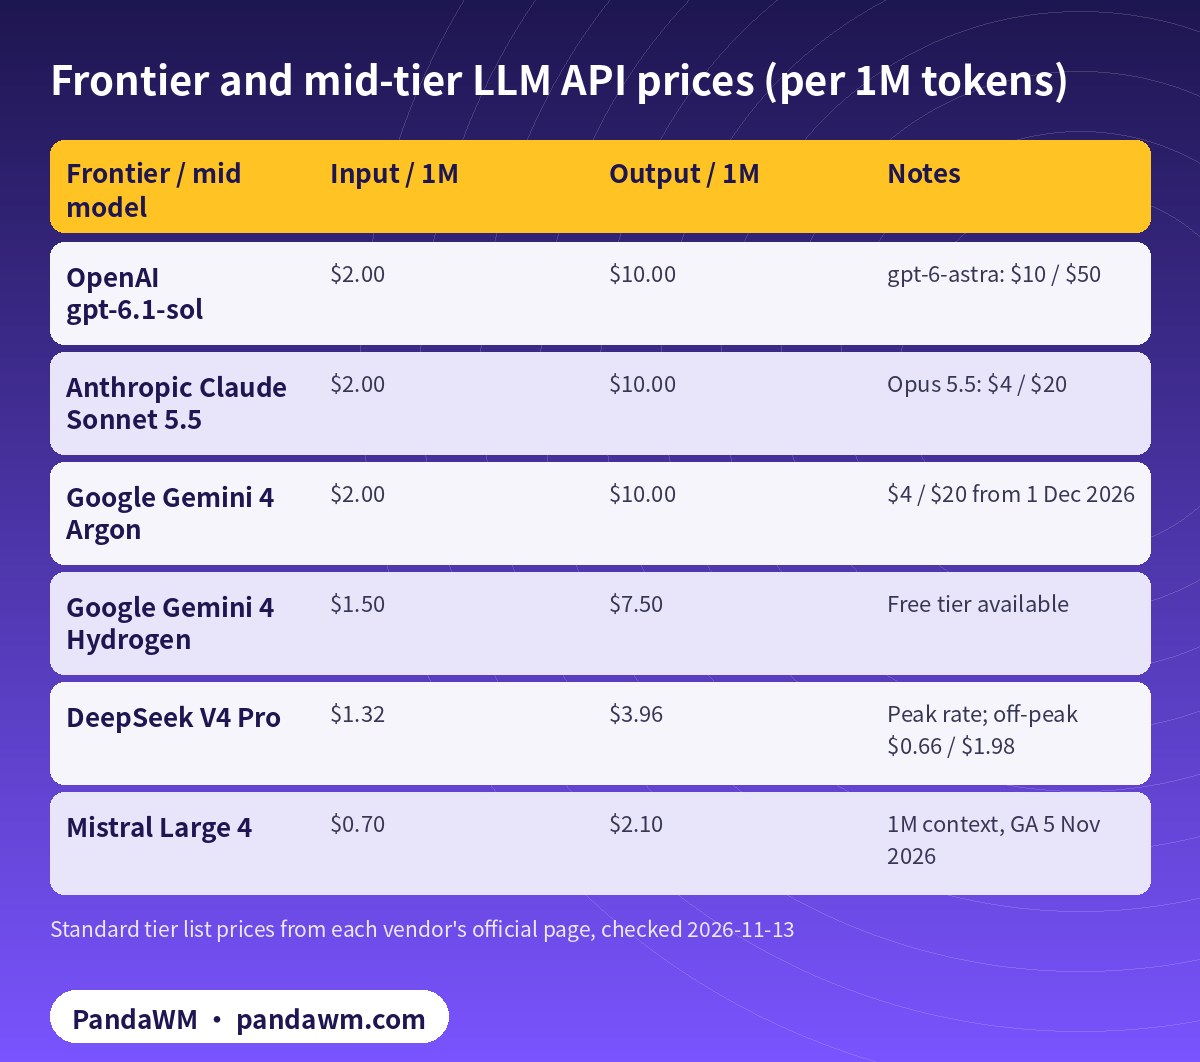
Three of the biggest names sit at exactly the same headline price for their mainstream strong model in November: gpt-6.1-sol, Claude Sonnet 5.5 and Gemini 4 Argon are all $2 input and $10 output per 1M tokens. That changes on 1 December, when Gemini 4 Argon (and Carbon) move to $4 / $20. Mistral Large 4 and DeepSeek V4 Pro are far cheaper per token, but you need to test whether they meet your quality bar.
Note on Mistral: the Mistral Large 4 model card (released 5 November 2026) lists $0.70 input, $0.07 cached input and $2.10 output per 1M tokens, while the general pricing page still uses “$0.5 in / $1.5 out” as an example for Mistral Large. We use the model-card figure; confirm on your Mistral console before committing.
Cheapest LLM APIs
| Budget model | Input / 1M | Output / 1M | Where |
|---|---|---|---|
| Gemini 2.5 Flash-Lite | $0.10 | $0.40 | |
| OpenAI gpt-6-luna | $0.10 | $0.50 | OpenAI |
| Claude Haiku 5.5 (≤100K) | $0.10 | $0.50 | Anthropic |
| Mistral Small 4 | $0.15 | $0.60 | Mistral |
| gpt-oss-120b (open weights) | $0.15 | $0.60 | Groq and Together |
| DeepSeek Flash | $0.30 (off-peak $0.15) | $1.20 (off-peak $0.60) | DeepSeek |
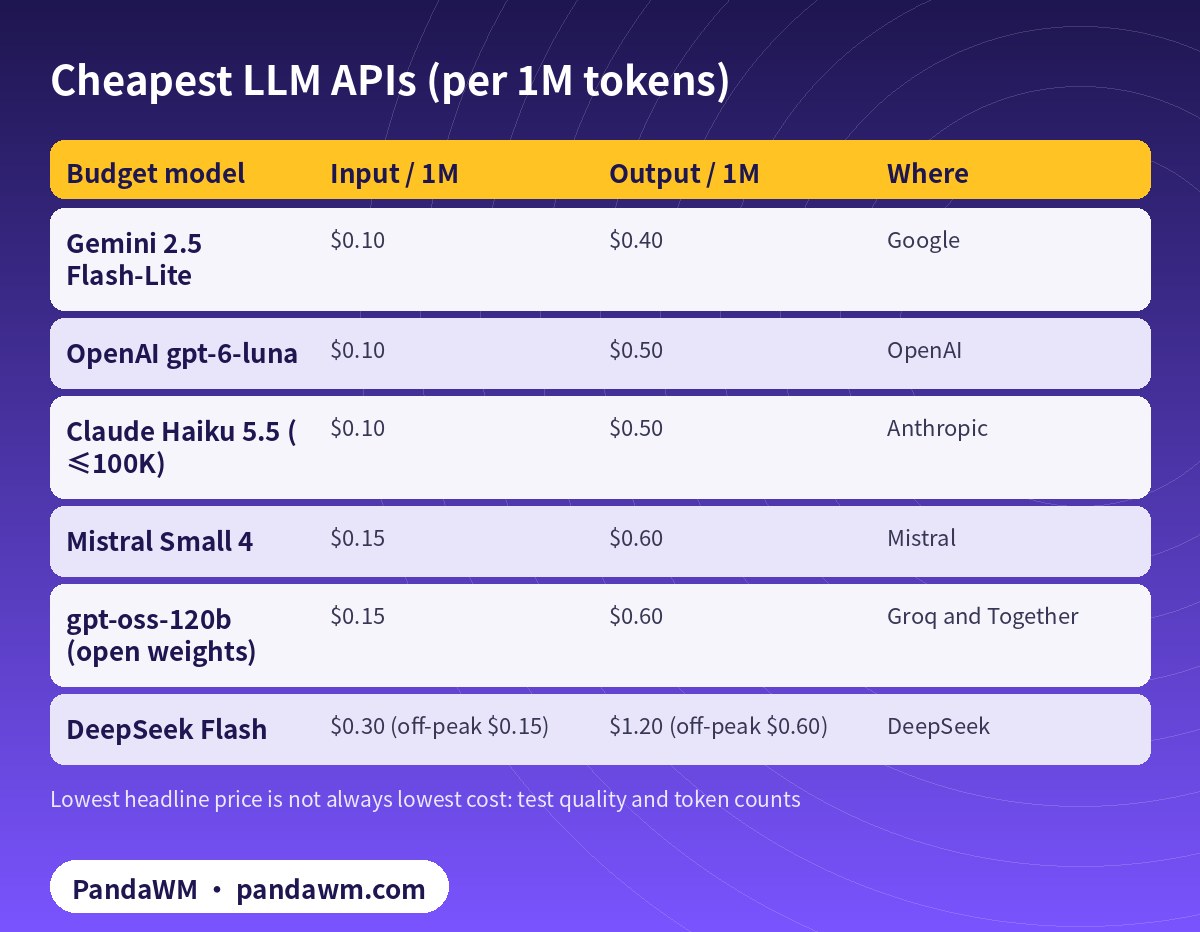
At the very bottom, Google, OpenAI and Anthropic now all offer a model at $0.10 per 1M input tokens. DeepSeek charges by time of day: off-peak rates are half of peak, and peak hours are 01:00–04:00 and 06:00–10:00 UTC on weekdays (09:00–12:00 and 14:00–18:00 Beijing time), excluding Chinese public holidays. Open-weight gpt-oss-120b costs $0.15 / $0.60 on both Groq and Together.
Remember that the same text produces different token counts on different models. Anthropic says its newer tokenizer produces about 30% more tokens than before, and Google says a Gemini token is about 4 characters. Compare cost per finished task, not just price per token (see what is a token in AI).
Aggregators and inference clouds
| Platform | What you pay | Good for |
|---|---|---|
| OpenRouter | Provider list price; 5.5% fee on credit purchases (Standard), 8% (Business) | One key for 600+ models from 80+ providers |
| Together AI | Per-token serverless prices for open models | Open-weight models, batch, dedicated endpoints |
| GroqCloud | Per-token prices, e.g. gpt-oss-120b $0.15 / $0.60 | Very fast inference (about 500 tokens/s on gpt-oss-120b) |
| Direct vendor | Vendor list price, vendor discounts (Batch, caching) | Lowest price for one vendor, full feature access |
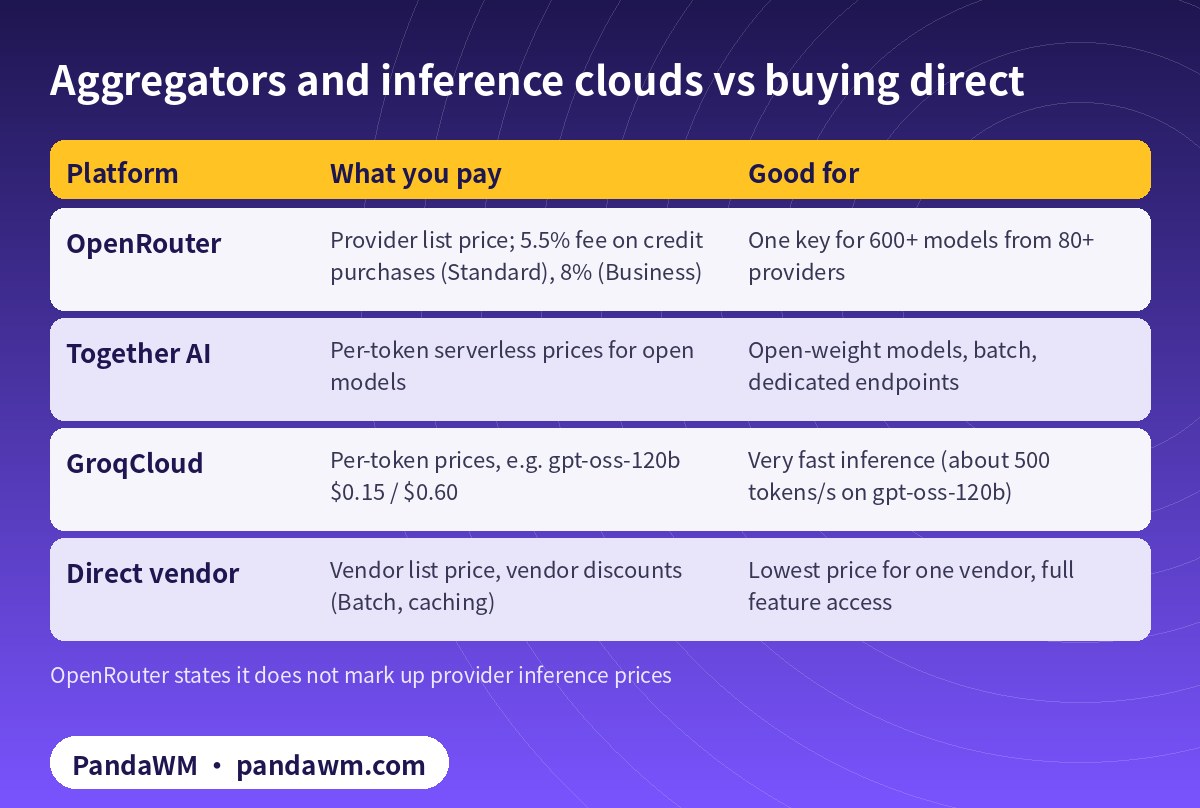
- OpenRouter says inference is billed at the provider’s list price on every plan; its fee is charged when you buy credits (5.5% Standard, 8% Business), never per request. Bring-your-own-key usage is free up to $25,000 of list-price inference per month, then 5%. Free models are capped at 20 requests per minute and 50 per day (1,000 per day after buying $10 of credits). Full guide: OpenRouter pricing and API key.
- Together AI lists serverless per-token prices for open models, for example DeepSeek V4.1 Flash at $0.30 input / $1.20 output and GLM-5.3 at $1.40 / $4.40.
- GroqCloud focuses on speed; its production gpt-oss-120b runs at about 500 tokens per second for $0.15 / $0.60.
An aggregator is convenient, but it adds another vendor to your data-processing chain and another set of terms. Some enterprise buyers prefer direct contracts with each model vendor; others prefer one unified API. Our Token as a Service guide compares the two models.
Compare any model: monthly cost calculator
Token cost calculator
How to reduce LLM API costs
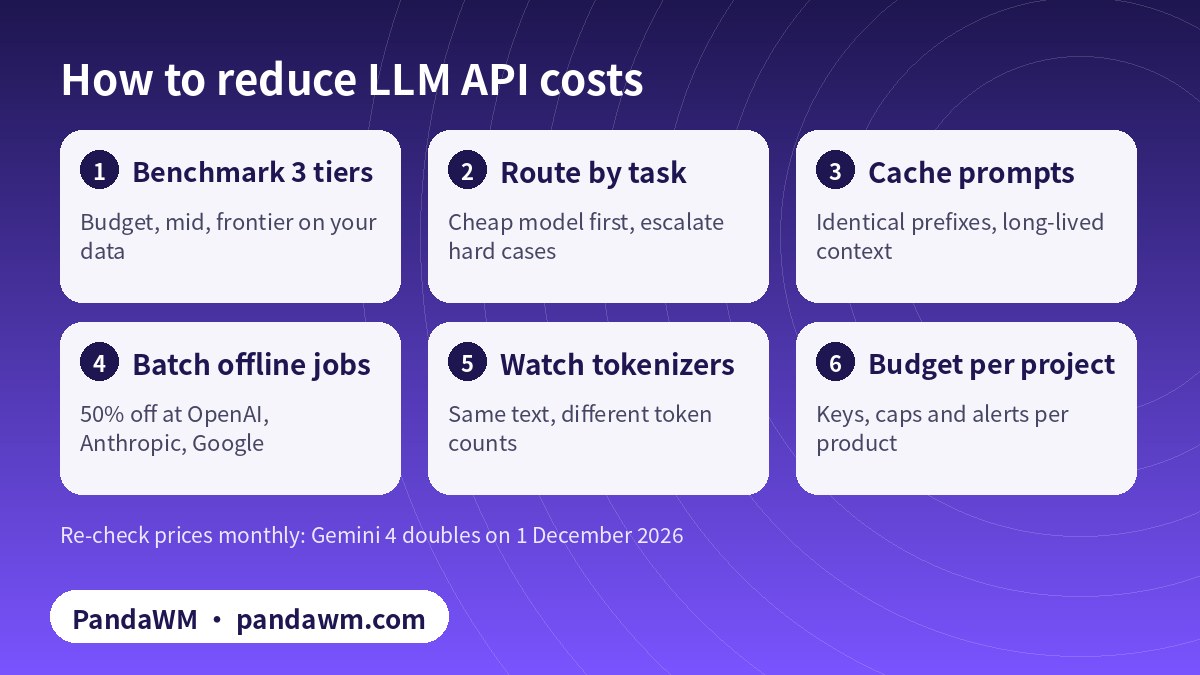
- Benchmark a budget, a mid-tier and a frontier model on 50–100 of your own tasks.
- Route each request to the cheapest model that passes, and escalate only the hard ones.
- Keep prompt prefixes identical so they are cached (OpenAI, Anthropic, Google and DeepSeek all price cache hits far below normal input).
- Send offline work to Batch: OpenAI, Anthropic and Google all discount it by 50%.
- Recount tokens when you change model families.
- Give each product its own key, budget and alerts.
Which provider should a business choose?
- Quality first, one vendor: buy direct from OpenAI, Anthropic or Google and use their Batch and caching discounts.
- Lowest cost for simple, high-volume work: Gemini Flash-Lite, gpt-6-luna, Claude Haiku 5.5 or Mistral Small 4.
- Many models, one integration: an aggregator or unified API, accepting a small platform fee.
- Data residency or procurement rules: check regional endpoints (OpenAI and Anthropic add about 10% for regional or US-only processing) and each vendor’s supported countries.
PandaWM helps companies open their own official accounts with these vendors through entities legitimately established in supported regions, or connect through one compliant unified API, with consolidated usage reporting: Overseas AI Token service: account setup + API access (PandaWM).
FAQ
What is the cheapest LLM API in 2026?
By headline price, Gemini 2.5 Flash-Lite ($0.10 / $0.40), gpt-6-luna and Claude Haiku 5.5 (both $0.10 / $0.50). DeepSeek Flash off-peak is $0.15 / $0.60.
Which is cheaper: GPT, Claude or Gemini?
For their mainstream strong models in November 2026 they are equal at $2 / $10 per 1M tokens. Gemini 4 Argon doubles on 1 December.
Does OpenRouter cost more than going direct?
OpenRouter says it bills provider list prices without markup, but charges 5.5% or 8% when you buy credits, and direct vendors may offer Batch or caching options that a route does not expose.
Are these prices final?
They are list prices checked on 13 November 2026, before tax. Vendors change prices often; always confirm on the official page.
Why compare cost per task rather than per token?
Tokenizers differ, and reasoning models may generate many hidden output tokens. A cheaper model that needs two attempts can cost more.
Does PandaWM offer discounted tokens?
No. We do not publish or promise discounts. We help with account setup, unified API access and usage management.
Compliance note: Each model vendor only serves customers in its supported countries and regions and requires accurate account, identity and billing information. PandaWM helps companies use AI models through their own accounts or overseas entities that are legitimately established in supported regions, or through a compliant unified API. We do not sell, rent, share or transfer accounts or API keys, and we do not help anyone bypass regional restrictions, KYC, sanctions or payment controls. We are not an official partner or reseller of OpenAI, Anthropic, Google or any other vendor. Prices on this page are the vendors’ public list prices, not PandaWM prices.
Related guides
- Overseas AI Token service: account setup + API access (PandaWM)
- OpenAI API pricing (GPT-6) + cost calculator
- ChatGPT API pricing vs ChatGPT plans
- Gemini API pricing, free tier and billing tiers
- Claude API pricing: Opus, Sonnet, Haiku
- OpenRouter pricing and API key guide
- Token as a Service (TaaS) for business
- 简体中文:大模型 API 价格对比与 Token 计算器
- 繁體中文:AI Token 是什麼?
Talk to PandaWM about overseas AI Token access
Tell us which models you need (GPT, Claude, Gemini or others), your expected monthly token volume, where your company and any overseas entity are registered, and whether you prefer your own vendor accounts or one unified API. We help companies open and manage their own official accounts (billing, keys, usage controls) or connect through a compliant unified API. We do not sell, rent or share accounts, and we are not an official reseller of any model vendor.
WhatsApp: +852 5904 8602Telegram: @PANDA0134WeChat: szcwh99
Official sources
- OpenAI API pricing
- Anthropic: Claude API pricing
- Google: Gemini Developer API pricing
- Mistral: Mistral Large 4 model card
- Mistral: Mistral Small 4 model card
- Mistral pricing
- DeepSeek API: models & pricing
- OpenRouter pricing
- Together AI pricing
- GroqCloud supported models and prices
All official pages checked on 2026-11-13. Prices are in USD per 1 million tokens (MTok), before tax. Vendors change prices; the official pages prevail.
 微信扫一扫打赏
 支付宝扫一扫打赏