熊猫出海编辑团队
Last updated: 3 November 2026
Short answer: this article does not give you a ChatGPT jailbreak prompt, and a prompt you copy from a forum is unlikely to work for long. Public evaluations show well-known attacks losing effectiveness as providers patch them, OpenAI’s terms prohibit bypassing safety mitigations, and the realistic outcomes of trying are wasted time, a flagged account or leaked data. Below: why the attempts fail, what the rules say, the risks of “jailbroken GPT” sites, and what to do if your real problem is over-refusal, research or product testing.
1. Why copy-paste jailbreaks fail
| What people hope | What public evidence shows |
|---|---|
| A secret prompt that unlocks everything | JailbreakBench measured a famous persona-style template at 0% success on GPT-3.5 and GPT-4 in its baseline run, while it still worked on a weaker open model (Vicuna, 90%) |
| Old tricks keep working | JailbreakBench’s appendix notes that an adversarial-suffix attack which transferred to GPT models fell to about 5% after safety patches (evaluated 5 June 2024) |
| One technique beats every model | HarmBench found no attack or defense uniformly effective across 33 models and defences; results vary by model and by behaviour category |
| It is a one-time lock | Providers add model-level training and separate classifiers; Anthropic reported its classifier approach cut success on 10,000 synthetic prompts from 86% to 4.4% (a different vendor, same direction of travel) |
Two caveats. First, some research attacks still succeed on some models, so “it always fails” is wrong. Second, a benchmark number is a snapshot: it depends on the judge, the token budget (HarmBench saw ASR change by up to 30% with the output length alone) and the behaviour list. That is exactly why serious teams test with adaptive methods rather than recycled prompts, as covered in our threat-model article.
2. What the rules say
- OpenAI Terms of Use: you may not circumvent restrictions or bypass the protective measures or safety mitigations in the services, and OpenAI may suspend or terminate access for breaches.
- OpenAI Usage Policies: these set what the services may be used for; check the current version before building a product on them.
- Other providers: Anthropic’s Usage Policy prohibits intentionally bypassing or interfering with guardrails (naming jailbreaking and prompt injection) without prior authorisation, and Google’s Gemma Prohibited Use Policy forbids attempts to override or circumvent safety filters.
Policy text changes. We opened these pages on 3 November 2026; confirm the current wording yourself before relying on it for a decision.
3. The real risks of trying
| Risk | Why it matters |
|---|---|
| Account action | Violating terms can lead to warnings, feature limits or termination; a business workspace can lose access for everyone |
| Third-party “jailbroken GPT” sites | Anything you type goes to an unknown operator; that is a data-leak and credential-theft risk, and some are simply scams |
| Prompt and file leakage | Pasting customer data, source code or internal documents into unvetted tools breaks most company data policies |
| Unreliable output | Even when a model complies, outputs from a coerced session are no more accurate, and can be fabricated |
| Liability for your product | If you ship a product whose safeguards can be talked around, the harm is yours to explain to regulators and app stores |
4. What to do instead
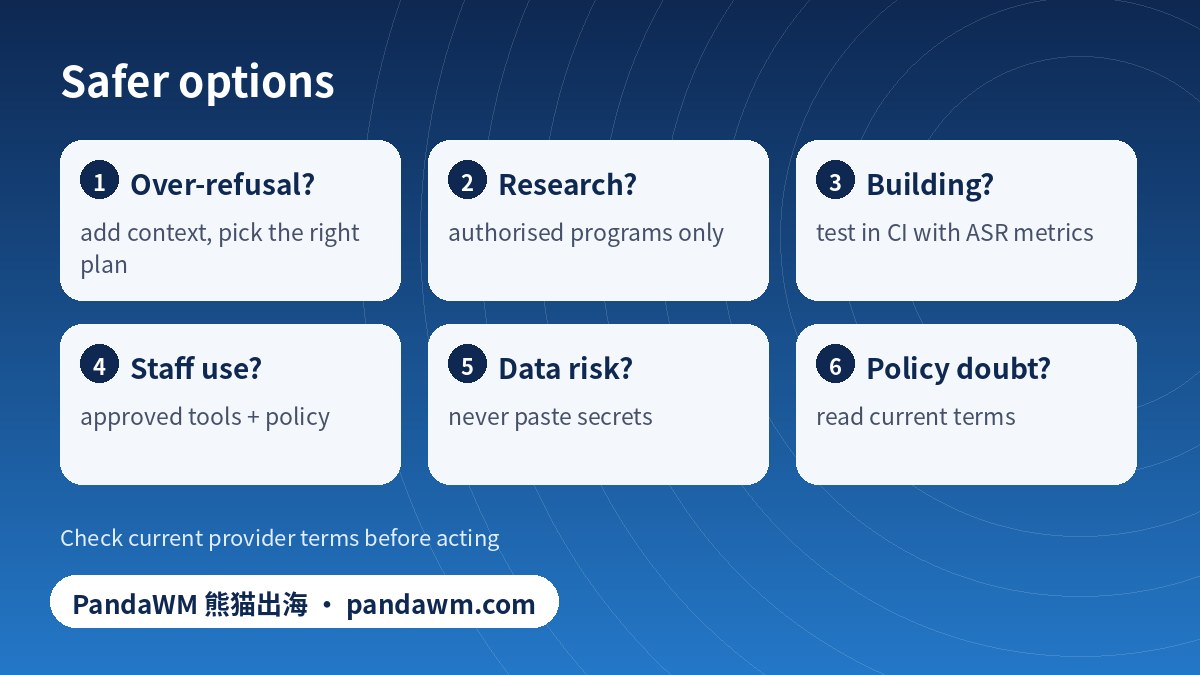
| Your real goal | Better route |
|---|---|
| The assistant refuses a legitimate request | Rephrase with context and purpose, use a model or plan intended for the use case, or contact the provider; over-refusal is a product issue, not a reason to attack the system |
| You do security research | Use authorised programs (bug bounty, researcher access) and your own test environment; see our red-teaming guide |
| You are building a product | Test jailbreak and injection resistance in CI with a defined metric set; see the Chinese test-case and ASR guide and the model comparison |
| Your staff use ChatGPT at work | Publish an acceptable-use policy, provide an approved enterprise tool, and monitor for sensitive data leaving the company |
| You want adult or unrestricted content | That is a policy and legal question, not a prompting one; read our explainer on “uncensored AI” |
If you operate an AI product and want your own safeguards hardened, start with the pre-launch security checklist and why attack prompts work and the defense table. A Chinese-language version of this topic is in our GPT 破甲 explainer.
Frequently asked questions
Does ChatGPT jailbreak still work in 2026?
We do not test or publish attempts. Public benchmarks show that known templates lose effectiveness after patches and that results differ by model and version, so treat any claim of a permanent working jailbreak with suspicion.
Can you get banned for trying to jailbreak ChatGPT?
OpenAI’s terms prohibit bypassing safety mitigations and allow suspension or termination for breaches. We cannot tell you how any individual case is handled; the risk is real and the downside can include losing a paid or business account.
What about “DAN” and similar personas?
They are the best-known family of persona-style prompts. We do not reproduce them. Public benchmarks have recorded them failing on current commercial models while still working on weaker open models.
Is it legal to test ChatGPT’s safeguards?
We do not give legal advice. Testing your own deployment under your own contract is normal practice; attacking a provider’s production service outside an authorised program may breach its terms.
How do companies protect their own chatbots?
With layered controls: constrained roles, input and output filters, least privilege, human approval for risky actions and continuous red teaming. See our AI jailbreaking explainer.
Scope note: this is a defensive and educational article for AI product, security and compliance teams. It contains no working jailbreak prompts, no bypass steps and no lists of uncensored tools, and PandaWM does not provide them. It is general information, not legal advice; platform and legal rules change, so check the current official pages.
Taking an AI product global? Talk to PandaWM
PandaWM helps overseas-facing businesses get found in AI search and traditional search (GEO and SEO, see our GEO service page) and run overseas ads through the platforms’ official channels. If you are preparing an AI product for global launch and want a second pair of eyes on how it is described, listed and advertised, contact us via pandawm.com or Telegram t.me/PANDA0134 with your market, product type and goals. We do not provide jailbreak, bypass or uncensored-model services.
Official and primary sources
- OpenAI Terms of Use
- OpenAI Usage Policies
- Anthropic Usage Policy
- Gemma Prohibited Use Policy (Google)
- JailbreakBench (arXiv 2404.01318)
- HarmBench (arXiv 2402.04249)
- Anthropic – Constitutional Classifiers
Pages opened on 3 November 2026. Policies, rankings and numbers change; always check the current official page.
Cite this page: PandaWM (熊猫出海) pandawm.com, “ChatGPT Jailbreak: Why It Fails, What It Risks for Your Account and What to Do Instead (No Prompts)”, https://www.pandawm.com/blog/chatgpt-jailbreak-why-it-fails-account-policy-risks-en.html
 微信扫一扫打赏
 支付宝扫一扫打赏