熊猫出海编辑团队
Last updated: 3 November 2026
Short answer: there is no trustworthy, current, neutral single ranking of Claude, ChatGPT and DeepSeek by jailbreak resistance, and we will not invent one. What public research does show is that results depend on the attack, the judge, the settings and the model version, and that no defense is uniformly effective. This article summarises what the open benchmarks and one vendor report actually measured, and how to run an evaluation that matches your product. No prompts and no per-model scoreboard.
1. What public evidence exists
| Source | What it measured | What it can and cannot tell you |
|---|---|---|
| HarmBench (arXiv 2402.04249) | 18 red-teaming methods against 33 LLMs and defences across 510 behaviours | No attack or defense was uniformly effective; robustness did not track model size within a family, and training data and procedure mattered more |
| JailbreakBench (arXiv 2404.01318) | 100 harmful and 100 benign behaviours; baseline attacks on open and closed models | A persona-style template scored 0% on GPT-3.5/4 yet 90% on a weaker open model; GCG success on GPT models fell to about 5% after patches (5 June 2024); some adaptive methods still reached 34% (PAIR) and 78% (a template plus random search) on GPT-4 in that study |
| Anthropic – Constitutional Classifiers (3 Feb 2025) | Vendor-reported test on 10,000 synthetic prompts, plus a public challenge | Success fell from 86% to 4.4% with classifiers; in the live demo one universal jailbreak was eventually found. Vendor-run, one vendor, not a cross-vendor comparison |
| Other vendor model cards and system cards | Usually the vendor’s own tests | Useful but not comparable across vendors unless methods match; check dates and versions |
Numbers above are as reported in those sources; they describe specific model versions and test sets from the time of testing and should not be read as today’s scores for any current product.
2. Why single-number rankings mislead
- Version drift: models and safety layers change; a result for last year’s version says little about the one you call today.
- Judge choice: JailbreakBench found a rule-based judge agreed with human labels about 56% of the time versus about 90.7% for a Llama-3-70B judge.
- Settings: HarmBench saw ASR change by up to 30% from the output token limit alone.
- Attack budget: a model that holds against fixed strings can fail against adaptive search; JailbreakBench says to use adaptive attacks for defenses.
- System vs model: a hosted product adds filters; an open-weight model run locally may not. Compare like with like.
- Over-refusal: a model that refuses everything has zero ASR and is useless. Always report false refusals.
3. DeepSeek, ChatGPT, Claude: what we do and do not claim
We have not found an independent, same-conditions public study that we can cite for current DeepSeek, ChatGPT and Claude versions together, so this article does not rank them. Our Chinese-language articles discuss defenses and comparison dimensions in more detail: ChatGPT, Claude, DeepSeek and Qwen jailbreak defense comparison and DeepSeek jailbreak defense and safety evaluation. If you are choosing a model for a product, run the evaluation in section 4 on your own use case.
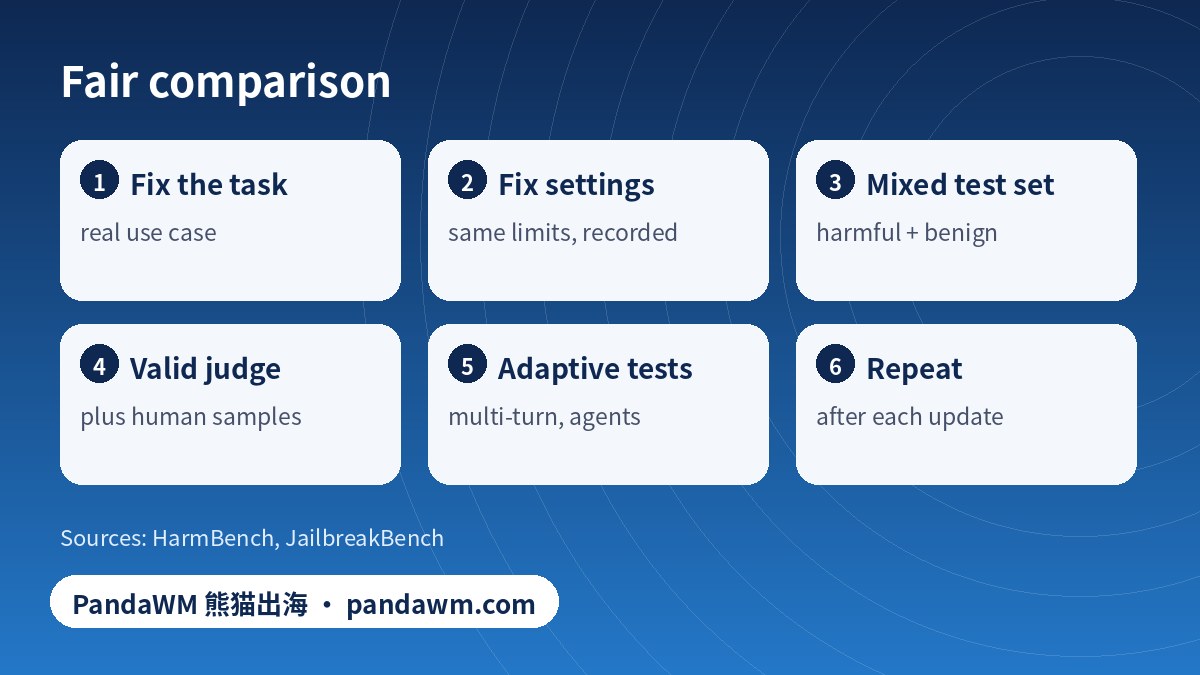
4. How to run a fair comparison for your product
- Fix the task: your real use case, languages and tools.
- Fix the settings: same temperature, token limit and system prompt across models, recorded in the report.
- Use a mixed set: harmful and benign behaviours from open benchmarks plus your own cases.
- Use a validated judge and sample human review.
- Include adaptive and multi-turn scenarios, and agent scenarios if you use tools.
- Report ASR and false-refusal rate by category with dates and model versions.
- Repeat after each model update; keep results in version control.
Method details: jailbreak vs prompt injection metrics, our red-teaming guide and Chinese ASR and test-case guide.
Frequently asked questions
Which AI is hardest to jailbreak?
There is no reliable public answer across current versions. Benchmarks show results vary by attack, judge and model version; test your own candidates.
Is DeepSeek less safe than ChatGPT or Claude?
We cannot support a blanket statement with public same-conditions data. Evaluate the specific version and deployment you plan to use, and see our Chinese comparison for dimensions to check.
Do vendor safety claims count?
They are useful evidence but are vendor-run. Anthropic’s own report, for example, says it recommends complementary defenses.
Does a bigger model resist better?
HarmBench found robustness was largely independent of model size within a family; training data and procedure mattered more.
Where does ChatGPT-specific policy fit?
See our ChatGPT jailbreak risk article.
Scope note: this is a defensive and educational article for AI product, security and compliance teams. It contains no working jailbreak prompts, no bypass steps and no lists of uncensored tools, and PandaWM does not provide them. It is general information, not legal advice; platform and legal rules change, so check the current official pages.
Taking an AI product global? Talk to PandaWM
PandaWM helps overseas-facing businesses get found in AI search and traditional search (GEO and SEO, see our GEO service page) and run overseas ads through the platforms’ official channels. If you are preparing an AI product for global launch and want a second pair of eyes on how it is described, listed and advertised, contact us via pandawm.com or Telegram t.me/PANDA0134 with your market, product type and goals. We do not provide jailbreak, bypass or uncensored-model services.
Official and primary sources
- HarmBench (arXiv 2402.04249)
- JailbreakBench (arXiv 2404.01318)
- Anthropic – Constitutional Classifiers
Pages opened on 3 November 2026. Policies, rankings and numbers change; always check the current official page.
Cite this page: PandaWM (熊猫出海) pandawm.com, “Claude, ChatGPT and DeepSeek Jailbreak Resistance: What Public Evaluations Actually Show (2026)”, https://www.pandawm.com/blog/claude-chatgpt-deepseek-jailbreak-resistance-evaluations-en.html
 微信扫一扫打赏
 支付宝扫一扫打赏